Veltron
Choosing an ai inference server manufacturer is no longer a simple hardware comparison. Global buyers must examine performance, reliability, service coverage, and long-term operating costs.
Inference happens where models meet real users. A customer request may travel through a server room, trigger several accelerators, and return an answer within milliseconds. Small delays become expensive at scale. Power consumption matters too, especially in regions with high electricity prices or limited data-center capacity. Jensen Huang, founder and CEO of NVIDIA, has described the market clearly: “The future of AI is inference.” His statement reflects a practical shift from training impressive models toward serving them efficiently every day.
This guide compares leading manufacturers through measurable and business-focused criteria. These include accelerator compatibility, memory capacity, cooling design, software support, security features, warranty terms, and regional deployment experience. A strong supplier should provide more than attractive benchmark numbers. Buyers also need clear documentation, responsive technical support, and realistic delivery commitments.
Yet no manufacturer is perfect. A system that performs well in a laboratory may struggle with heat, network congestion, or software updates. Benchmark results can also hide important assumptions. Some vendors publish incomplete pricing or test only favorable workloads. That deserves caution.
The right ai inference server manufacturer depends on workload, budget, location, and growth plans. Our comparison aims to make those trade-offs visible. It does not promise one universal winner. Real deployments are messier than product brochures.
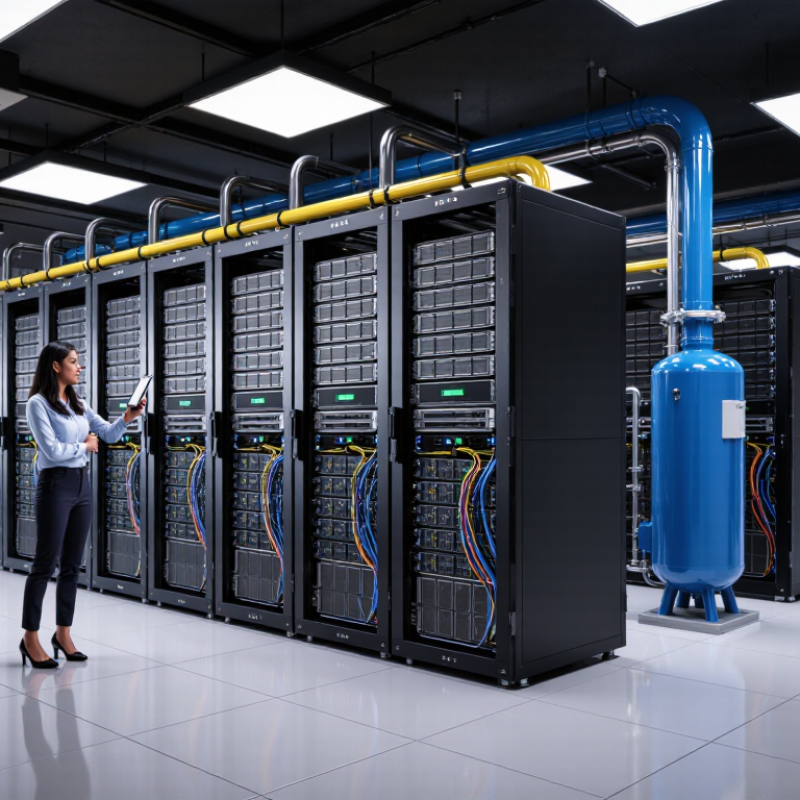
AI inference servers run trained models after deployment, turning user prompts, images, or sensor data into responses. Their purpose is practical: deliver low-latency predictions at controlled operating costs. A production server may process thousands of requests while maintaining a strict response-time target. It is not merely a powerful computer. It is a carefully balanced system.
The architecture usually combines accelerators, high-speed memory, multi-core processors, storage, and fast networking. GPUs or other AI accelerators execute parallel matrix operations, while CPUs manage requests, security checks, and data preparation. Large memory capacity keeps model weights available without repeated storage access. Quantization can reduce memory usage, although accuracy may decline in difficult cases. This trade-off is often underestimated. Stanford’s AI Index 2025 reported that GPT-3.5-level inference costs fell from 20 dollars to 0.07 dollars per million tokens between November 2022 and October 2024, a roughly 280-fold reduction.
Core components also include inference runtimes, model servers, monitoring tools, and cooling systems. Software schedules batches, controls concurrency, and measures latency, throughput, and error rates. MLCommons’ MLPerf Inference benchmarks reflect these performance differences under standardized workloads. Energy remains a hard constraint. The International Energy Agency projects global data-centre electricity demand could rise from about 415 TWh in 2024 to approximately 945 TWh by 2030. Buyers should examine performance per watt, not peak speed alone. Real workloads are messier.
Top AI Inference Server Manufacturers for Global Buyers
Choosing an AI inference server manufacturer requires more than comparing processor counts. In deployment reviews, examine latency at the 95th and 99th percentiles, not only average response time. Small delays become visible when support queues receive thousands of requests. Measure real workloads. A useful evaluation starts with model compatibility, memory capacity, accelerator options, and software support. The system should run intended models without extensive code changes. Clear documentation also reduces installation errors.
Independent benchmarks provide a starting point, but buyers should request workload-specific tests. Peak throughput can look impressive. It may collapse under mixed requests, limited memory, or thermal throttling. I once favored a high headline score and underestimated power costs. That judgment needed revision. Ask manufacturers for sustained performance data, power readings, failure rates, and upgrade paths. Check whether results used realistic batch sizes and production-like inputs. Reproducible evidence is more valuable than polished slides.
Reliability also depends on service quality. Evaluate warranty terms, spare-part availability, firmware updates, security controls, and technical support response times. Ask who handles diagnostics when a server fails overnight. A practical trial should run for several days, with monitoring enabled and recovery procedures documented. Inspect noise, rack space, cooling requirements, and network compatibility before purchasing. These physical details are easy to ignore. They can determine whether a promising server performs smoothly in a real data center.
| Evaluation Dimension | What to Evaluate | Relevant Technical Indicators | Practical Benchmark or Requirement | Recommended Verification Method |
|---|---|---|---|---|
| Inference Performance | The server’s ability to process model requests quickly and consistently. | Time to first token, token generation rate, requests per second, p95 and p99 latency. | Set separate targets for interactive, batch, and real-time workloads; do not rely on peak throughput alone. | Run standardized tests using the intended model, input length, output length, concurrency, and quantization settings. |
| Accelerator Capability | Suitability of the installed GPU, AI accelerator, or other processing hardware for the target workload. | Compute precision, memory bandwidth, tensor or matrix performance, accelerator count, and interconnect speed. | Choose hardware according to model size, sequence length, concurrency, and required precision rather than accelerator count alone. | Review published specifications and validate end-to-end application performance with representative traffic. |
| Memory Capacity | Whether system memory and accelerator memory can hold the model, weights, runtime, and key-value cache. | Accelerator memory capacity, system RAM, memory bandwidth, and available memory after system overhead. | Allow headroom for longer context windows, concurrent sessions, model updates, and operating-system overhead. | Calculate peak memory usage and conduct stress tests at the planned maximum concurrency. |
| Model and Software Compatibility | Support for the frameworks, runtimes, operating systems, and model formats required by the buyer. | Support for common model formats, container platforms, orchestration tools, drivers, and inference engines. | The complete software stack should support the selected models without mandatory proprietary dependencies. | Request a compatibility matrix and deploy a proof-of-concept using the production software stack. |
| Scalability | Ease of expanding capacity as model usage, users, or geographic coverage increases. | Rack density, multi-server deployment, horizontal scaling, load balancing, and accelerator interconnects. | The architecture should support incremental expansion without requiring a complete redesign. | Evaluate a scale-out test, capacity-planning model, network topology, and future upgrade paths. |
| Energy Efficiency | Performance delivered for the electricity consumed by the server and facility. | Performance per watt, total system power, thermal design power, power capping, and cooling requirements. | Compare energy per request or energy per generated token under the same workload conditions. | Measure power at idle and during sustained inference; include cooling and facility power in total-cost calculations. |
| Reliability and Availability | The server’s ability to operate continuously and recover from component or software failures. | Component quality, redundant power supplies, hot-swappable parts, error reporting, and failure recovery. | Require documented service-level targets and a recovery plan appropriate to the application’s business impact. | Review failure-rate data, warranty terms, diagnostic tools, and results from failover or hardware-removal tests. |
| Security | Protection of models, user prompts, generated outputs, credentials, and management interfaces. | Secure boot, firmware controls, encryption, access management, audit logs, vulnerability response, and network isolation. | Security controls should align with the buyer’s regulatory, privacy, and internal-risk requirements. | Request security documentation, patch policies, software bills of materials, and independent compliance evidence where applicable. |
| Manageability | Tools available for deployment, monitoring, configuration, updates, and troubleshooting. | Remote management, telemetry, health monitoring, automation interfaces, logging, and integration with existing tools. | Routine operations should be possible remotely and consistently across multiple servers or locations. | Test installation, firmware updates, alerting, inventory management, rollback, and remote recovery procedures. |
| Deployment Flexibility | Compatibility with data centers, private infrastructure, edge locations, and hybrid environments. | Rack dimensions, power input, operating temperature, acoustic limits, network interfaces, and installation requirements. | Confirm that the server fits local rack, power, cooling, connectivity, and environmental constraints. | Use a site-readiness checklist and verify regional electrical, safety, and environmental certifications. |
| Total Cost of Ownership | The full cost over the expected service life, not only the initial purchase price. | Hardware, software, support, energy, cooling, networking, labor, upgrades, and downtime costs. | Compare cost per request, cost per token, or cost per completed workload at a defined utilization level. | Build a three-to-five-year financial model using realistic utilization, electricity, maintenance, and replacement assumptions. |
| Global Support and Supply Chain | Ability to deliver, install, maintain, and replace equipment across the buyer’s operating regions. | Regional support coverage, spare-parts availability, lead time, logistics capability, escalation process, and warranty response. | Require documented delivery timelines, local or regional service options, and a clear replacement process. | Check references from comparable regions and obtain written commitments for delivery, support, and spare parts. |
| Standards and Compliance | Conformity with applicable safety, electromagnetic compatibility, environmental, and procurement requirements. | Product certifications, energy regulations, restricted-substance requirements, export controls, and regional documentation. | All required certifications and import documents should be available before purchase and deployment. | Request current certificates, declarations, test reports, and country-specific compliance documentation. |
Note: Performance and cost results vary according to model architecture, precision, context length, concurrency, software configuration, utilization, electricity prices, and data-center conditions. Buyers should compare systems using identical workloads and measurement methods.
Leading AI Inference Server Manufacturers in the Global Market
Global buyers now assess AI inference server manufacturers beyond processor speed. They examine latency, power use, thermal design, and long-term service capacity. In field evaluations, stable performance often matters more than impressive peak benchmarks. A server may process thousands of requests per second in testing. Real workloads can behave differently.
Experienced manufacturers provide configurable systems for language models, computer vision, and industrial analytics. They support various accelerator options, memory capacities, networking standards, and storage layouts. Clear documentation helps technical teams install and maintain equipment across different regions. Reliable suppliers also publish test methods, warranty terms, delivery schedules, and spare-parts policies. These details reduce uncertainty.
Local support matters.
Global buyers should inspect factory quality controls and independent performance evidence. I would request workload-specific trials before placing a large order. A short demonstration cannot reveal every thermal or software problem. Power efficiency also deserves careful review, especially in dense data centers. Some manufacturers offer strong hardware but weaker integration guidance. That weakness can increase deployment time. Security updates, export procedures, regional certifications, and technician training should receive equal attention. No checklist is perfect. Buyers may still discover gaps after installation, so flexible service agreements remain valuable.
Regional availability matters as much as accelerator performance. The International Energy Agency reports that data centers consumed about 460 TWh of electricity in 2022. Demand could exceed 1,000 TWh by 2026. Buyers should therefore examine local power capacity, cooling design, and delivery timelines before selecting an inference server manufacturer. A fast machine is not useful if replacement parts remain overseas.
Support quality also varies by region. Gartner’s infrastructure research consistently links service outcomes with response time, spare-parts access, and qualified technicians. Ask whether support operates in your time zone. Confirm escalation procedures. Test the process before purchase. A phone number is not support.
Compliance requires deeper checks. The OECD AI Policy Observatory emphasizes risk management, transparency, and accountability across AI systems. International buyers should request documentation for data residency, hardware origin, firmware updates, and secure decommissioning. Export-control requirements may also affect shipment routes and component availability. Requirements differ by jurisdiction. Do not rely on a distributor’s verbal assurance. Written evidence is safer, though still imperfect. Procurement teams should compare energy certificates, security audits, warranty terms, and local repair capacity. A lower purchase price can hide customs delays, specialist travel costs, or months of downtime.
Choosing an AI inference server manufacturer starts with the workload, not the datasheet. Real-time video inspection needs predictable latency, high memory bandwidth, and strong thermal control. A customer-service model may prioritize concurrent sessions and low cost per request. Batch forecasting can accept slower responses but needs efficient throughput.
The numbers are moving quickly. Stanford’s AI Index 2024 reported that GPT-3.5-level inference costs fell from about $20 to $0.07 per million tokens between November 2022 and October 2023. That sharp decline changes purchasing logic. Buyers should compare total operating cost, not only server price.
MLPerf Inference results can help, but benchmark conditions rarely match a factory floor or hospital network. Test with your model, input size, and peak traffic.
For edge deployments, examine compact design, remote management, and operation during network outages. For centralized services, check accelerator memory, rack density, cooling, and software compatibility. Power deserves attention. The International Energy Agency estimated data centers consumed 460 TWh globally in 2022 and could exceed 1,000 TWh by 2026. Ask manufacturers for measured performance per watt. Also verify firmware support, security updates, spare-part availability, and response times. A polished demonstration is not enough. I would still require a paid pilot, because vendor estimates can be optimistic and my own assumptions may be wrong.
It runs trained models after deployment. It converts prompts, images, or sensor data into predictions. The goal is fast, affordable responses. It is not merely a powerful computer.
Common components include accelerators, CPUs, memory, storage, networking, and cooling systems. Accelerators handle parallel calculations. CPUs manage requests, security checks, and data preparation. Balanced design matters.
GPUs and similar accelerators execute many matrix operations simultaneously. This can reduce response delays and increase request capacity. However, peak speed may not match daily performance.
Large memory keeps model weights available during operation. This reduces repeated storage access. Quantization can lower memory use, but accuracy may decline in difficult cases. The trade-off is easy to underestimate.
Review latency, throughput, error rates, concurrency, and performance per watt. Standardized benchmarks can help compare systems. Test your own workload too. Real workloads are messier.
Dense servers can consume substantial electricity and generate intense heat. Buyers should check facility power, airflow, cooling capacity, and rack limits. A fast server is useless without stable cooling.
Confirm time-zone coverage, escalation procedures, spare-parts access, and qualified technicians. Ask how quickly failed components can be replaced. Test the support process before purchase. A phone number is not support.
Request evidence covering data residency, hardware origin, firmware updates, security reviews, and secure decommissioning. Check export requirements and regional certifications. Verbal assurances are insufficient. Written evidence is safer, though still imperfect.
Request a workload-specific trial before placing a large order. Review warranty terms, delivery schedules, service agreements, and local repair capacity. Examine thermal behavior during sustained operation. No checklist catches everything.
AI inference servers are specialized systems designed to run trained artificial intelligence models efficiently and deliver fast, reliable predictions. Their architecture typically combines powerful processors, accelerators, high-speed memory, optimized networking, storage, cooling, and software frameworks. When evaluating an ai inference server manufacturer, buyers should consider processing performance, energy efficiency, scalability, system reliability, customization options, lifecycle support, security, and total ownership cost.
Global buyers should also review regional availability, delivery capabilities, technical assistance, warranty terms, data protection practices, and compliance requirements. The leading manufacturers distinguish themselves through flexible configurations, dependable supply chains, and support for different deployment environments, including data centers, enterprise facilities, cloud infrastructure, and edge locations. Selecting the right supplier depends on workload size, model complexity, latency expectations, budget, expansion plans, and industry requirements. A careful comparison of technical specifications and long-term service capabilities can help organizations build a secure, efficient, and future-ready AI inference platform.