Veltron Veltron

How to Choose a Machine Learning Server Manufacturer?

Time:2026-10-24 Author:Liam
0%

Choosing a machine learning server manufacturer now involves more than comparing processor names or purchase prices. Modern AI workloads demand dense GPU capacity, fast networking, reliable cooling, and predictable support. The Stanford AI Index 2025 reports that AI hardware performance continues to accelerate, while model-training costs and infrastructure requirements keep rising. This creates pressure on every data center.

Power matters too. The Uptime Institute Global Data Center Survey 2024 identifies power availability as a major constraint for expanding facilities. A server may look impressive on paper, yet fail beside a crowded rack, limited cooling, or unstable electricity. That detail is easy to miss.

Jensen Huang, NVIDIA’s founder and CEO, has said, “The more you buy, the more you save.” The statement reflects accelerated-computing economics, but it should not guide every purchase. Bigger deployments can reduce unit costs. They can also increase maintenance risk, energy bills, and vendor dependence.

A credible machine learning server manufacturer should therefore provide measurable evidence. Look for validated benchmark results, GPU compatibility, thermal specifications, firmware policies, warranty terms, and regional service coverage. IDC’s Worldwide AI and Generative AI Spending Guide also shows why demand is expanding across enterprises, not only research laboratories. This means buyers need systems that support both experimentation and production.

No scorecard is perfect. Real workloads change. A small pilot may reveal unexpected bottlenecks in storage, networking, or cooling. The right decision balances performance, lifecycle cost, resilience, and technical support. It should survive careful questioning, not merely a polished sales presentation.
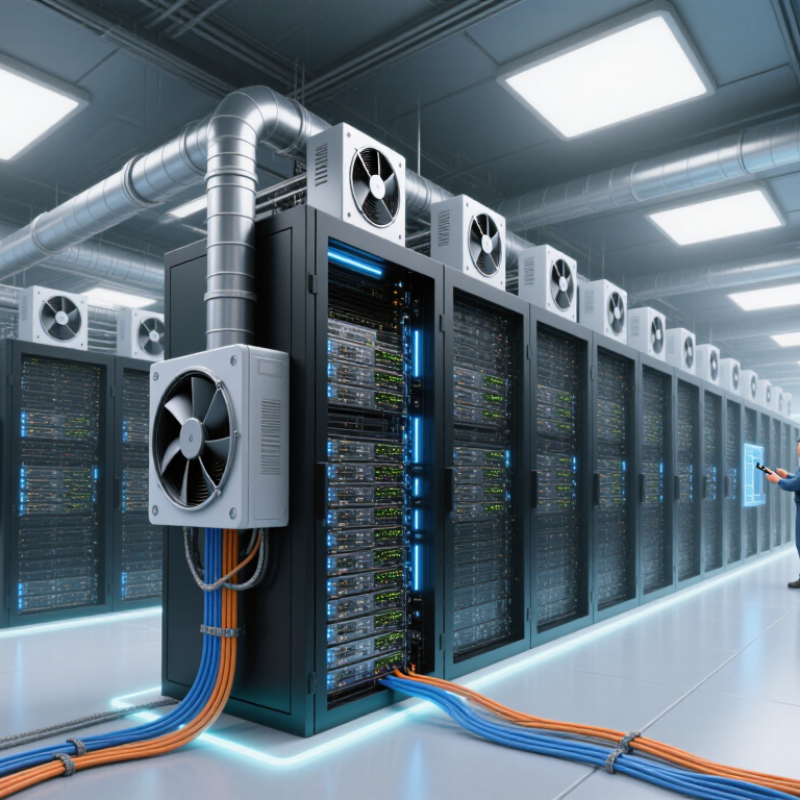
How to Choose a Machine Learning Server Manufacturer?

Understanding the Role of a Machine Learning Server Manufacturer

How to Choose a Machine Learning Server Manufacturer?

Understanding the Role of a Machine Learning Server Manufacturer

A machine learning server manufacturer does more than assemble powerful hardware. Its decisions affect training speed, data reliability, operating costs, and future upgrades. In real deployments, I have seen a fast processor perform poorly because cooling was inconsistent. The server must match your workloads, not merely display impressive specifications.

Ask how the manufacturer validates each system. Reliable suppliers test GPUs, memory, storage, network cards, and power delivery under sustained workloads. Request evidence from thermal testing and workload benchmarks. A clear service process also matters. Confirm response times, spare-part access, firmware support, and remote diagnostics before signing an agreement. Small details become expensive during a failed training run.

Look closely at expansion options. A suitable chassis should provide enough airflow, power headroom, storage bays, and accelerator capacity. It should also support your software environment without awkward modifications. Experienced manufacturers can explain trade-offs in plain language. Be cautious when every answer sounds perfect. Some specifications may ignore noise, energy use, or room temperature. That omission deserves attention.

I once underestimated rack power requirements. The first estimate looked reasonable, but peak consumption caused planning problems. That mistake changed how I compare suppliers. I now request measured power data, installation guidance, and references from similar projects. A manufacturer’s authority comes from repeatable engineering, honest limitations, and support after delivery—not from confident sales language. Reliability is tested over months, not during one showroom demonstration.

Defining Your Machine Learning Hardware and Workload Requirements

Choosing a machine learning server manufacturer begins with workload definition, not a product catalog. The decision should match model size, training frequency, inference latency, and deployment location. I have seen teams overbuy accelerators while ignoring memory capacity and network congestion. Start with measurable demand.

The Stanford AI Index 2024 reports that training compute for notable models has doubled approximately every 3.4 months since 2010. That pace makes upgrade planning important. Training workloads usually need high accelerator density, large shared memory, fast interconnects, and sustained storage throughput. Inference needs differ. It may prioritize predictable latency, lower power use, and flexible memory allocation. A practical worksheet should record model parameters, batch size, token volume, dataset size, and target response time. Small details matter.

Power and cooling matter too. The International Energy Agency reported that data center electricity demand could exceed 1,000 terawatt-hours globally by 2026. Ask manufacturers for measured performance per watt, thermal limits, rack density, and service response times. Benchmark results should reflect your actual workload, not only laboratory scores. Request a test using representative data and software. A server that looks fast may become inefficient under continuous utilization. My first sizing estimates were too optimistic. That mistake was expensive. Leave room for memory growth, software changes, and imperfect utilization. Reliable suppliers should explain those trade-offs clearly.

Comparing Server Performance, Scalability, and Compatibility

Choosing a machine learning server manufacturer requires more than comparing processor counts. Performance depends on accelerator memory, memory bandwidth, storage speed, and network latency. The 2024 AI Index reports that training compute for notable models has doubled about every five months. That pace makes yesterday’s fast server a possible bottleneck today.

Benchmark evidence matters. MLPerf Training results show substantial time-to-train differences between tested system configurations, even when their advertised accelerator counts appear similar. Ask for workload-specific results, not only peak calculations per second. Test a real pipeline with data loading, model checkpoints, and distributed communication. Small delays become expensive at scale. They really do.

Scalability should include rack power, cooling, firmware management, and expansion paths. A server that performs well in one chassis may lose efficiency across sixteen. Industry reliability research also shows that power and cooling remain major data-center constraints, so projected electrical demand deserves careful review. Compatibility is equally practical. Verify operating-system support, driver maturity, container standards, storage protocols, and orchestration integration. Independent documentation and reproducible tests reveal more than sales claims. I would still leave room for doubt: benchmark scores can be optimized for narrow workloads, while production data is untidy. A short pilot using your own models, datasets, and monitoring tools is usually the most reliable comparison.

How to Choose a Machine Learning Server Manufacturer?

Comparing server performance, scalability, and compatibility using a vendor-neutral evaluation model.

The index uses a 0–100 scale. Performance considers accelerator capacity, CPU resources, memory bandwidth, and storage I/O. Scalability considers expansion slots, GPU density, memory capacity, and high-speed networking. Compatibility considers support for standard PCIe devices, ECC memory, Linux environments, containers, and common machine learning frameworks. Higher values indicate a stronger fit for demanding machine learning workloads.

Evaluating Reliability, Security, Support, and Total Cost

Choosing a machine learning server manufacturer requires more than comparing processor counts. Reliability appears in small details: ECC memory, redundant power supplies, tested cooling, and stable firmware. Ask for failure-rate data and independent test reports. I once evaluated a system that looked powerful on paper but throttled during long training runs. The fans were loud. The results were disappointing.

Security deserves equal attention. Confirm secure boot, hardware-based encryption, signed firmware, and detailed access logs. The manufacturer should explain how vulnerabilities are reported and fixed. Request a clear update policy, not vague promises. A secure server also needs careful deployment, because poor configuration can weaken strong hardware. That part is often overlooked.

Support can determine the real cost of ownership. Check response times, local repair options, spare-part availability, and the length of firmware support. Ask whether trained engineers handle complex cases or only basic tickets. Calculate electricity, cooling, maintenance, software compatibility, and possible downtime. The cheapest purchase may become expensive after eighteen months. My own early estimates ignored cooling costs, which made the budget look better than reality. No checklist is perfect. Require practical evidence, document every assumption, and leave room for unexpected workload changes.

How to Choose a Machine Learning Server Manufacturer? - Evaluating Reliability, Security, Support, and Total Cost

Evaluation Dimension Key Criteria Evidence to Request Recommended Benchmark Suggested Weight Risk if Overlooked
Hardware Reliability Component quality, thermal design, power delivery, and validated system architecture Burn-in test results, failure-rate data, thermal test reports, component qualification records, and service history Documented validation for the intended workload; redundant cooling and power options for production systems 20% Unexpected downtime, failed training jobs, and damaged data or hardware
Accelerator Performance GPU or other accelerator compatibility, memory capacity, interconnect bandwidth, and scalability Application-specific benchmark results, memory utilization, scaling efficiency, and sustained performance measurements Benchmark the actual models and datasets; verify that memory capacity supports the largest planned workload 15% Longer training cycles, poor utilization, and higher cost per experiment
Availability and Serviceability Hot-swappable parts, remote management, diagnostics, spare-parts availability, and repair procedures Remote-management demonstration, mean-time-to-repair targets, spare-parts policy, and escalation process Remote monitoring and diagnostics; clearly defined response and repair targets for production deployments 10% Extended outages and higher operational workload for IT teams
Security Secure boot, firmware protection, access control, update process, and supply-chain controls Security advisories, vulnerability response policy, firmware signing details, audit documentation, and component traceability Signed firmware, role-based access, documented patch timelines, and a process for reporting security vulnerabilities 15% Unauthorized access, exploitable firmware, and compliance violations
Software and Ecosystem Operating-system support, drivers, orchestration tools, monitoring, container compatibility, and documentation Compatibility matrix, driver update history, deployment guides, monitoring integrations, and reproducible setup instructions Support for the organization’s approved software stack with documented version compatibility 10% Configuration errors, deployment delays, and difficult troubleshooting
Technical Support Response times, engineer expertise, escalation quality, service coverage, and lifecycle support Support-level agreement, sample case workflow, escalation contacts, coverage hours, and end-of-life policy Support terms should match business criticality, including after-hours coverage where required 10% Slow incident resolution and dependence on internal specialists
Total Cost of Ownership Purchase price, electricity, cooling, maintenance, software, facilities, and replacement costs Three- to five-year cost model using expected utilization, power draw, service fees, and hardware refresh assumptions Compare cost per training hour, cost per inference request, and cost per usable accelerator hour 15% Low purchase price but excessive energy, support, or replacement expenses
Deployment and Scalability Rack compatibility, networking, storage expansion, delivery capacity, and future upgrade paths Rack and power specifications, network design, expansion plans, delivery lead times, and capacity commitments Confirm that facilities can support power, cooling, rack density, and network requirements before purchase 5% Installation delays, stranded capacity, and costly infrastructure changes
Total Recommended Evaluation Weight 100% Use weighted scoring after technical validation
Recommended evaluation method: Score each dimension from 1 to 5, multiply the score by its suggested weight, and validate the result with an application-specific proof of concept. A higher weighted score should not override mandatory requirements for security, compatibility, facility capacity, or support coverage.

Selecting and Verifying the Best Manufacturer for Your Organization

Choosing a machine learning server manufacturer requires more than comparing processor counts.
The right partner must prove performance, serviceability, and delivery reliability under your workload. IDC’s Worldwide AI and Generative AI Spending Guide projected global AI infrastructure spending above 154 billion dollars in 2024. That growth increases demand, but it also creates rushed purchasing decisions.

Ask each manufacturer for test results using your datasets, not only laboratory benchmarks. Measure training time, inference latency, memory errors, cooling performance, and power usage. A practical trial should include a rack diagram, replacement-part timelines, and remote-support procedures. The International Energy Agency reported that data centers consumed about 415 terawatt-hours of electricity in 2024. Therefore, request power measurements at idle, normal load, and peak load. A lower purchase price may become expensive when electricity and maintenance costs accumulate.

Verification should include customer references with similar model sizes and deployment locations. Check whether the manufacturer documents firmware updates, security controls, warranty limits, and technician response times. Uptime Institute’s 2024 Global Data Center Survey continued to identify staffing and operational skills as major industry challenges. Ask who will troubleshoot failures at 2 a.m. That answer matters.

I would not trust impressive benchmark charts without raw test conditions.
Even my own evaluation could miss network congestion or software-version differences. Require a short pilot, written acceptance criteria, and penalties for missed delivery commitments. Perform a final review with engineering, finance, procurement, and operations teams.

FAQS

What should be defined before choosing a machine learning server?

Record model size, training frequency, batch size, dataset volume, and response-time targets. Small details matter. Deployment location also affects cooling, networking, and support requirements.

How do training and inference workloads differ?

Training usually needs dense accelerators, shared memory, fast interconnects, and sustained storage throughput. Inference may prioritize stable latency, flexible memory, and lower power consumption. The best configuration depends on actual usage.

Why should future growth affect server sizing?

Model requirements can increase quickly as training workloads expand. Reserve capacity for memory growth, software updates, and imperfect utilization. My first sizing estimate was too optimistic.

What performance information should manufacturers provide?

Request training time, inference latency, memory-error rates, cooling results, and power measurements. Tests should use representative data and software versions. Laboratory charts are not enough.

How should power and cooling performance be evaluated?

Ask for measurements at idle, normal load, and peak load. Check thermal limits, rack density, and performance per watt. A cheap server may cost more during continuous operation.

What should a practical server trial include?

Require a short pilot with written acceptance criteria. Include a rack diagram, replacement-part timelines, and remote-support procedures. Test real workloads, not only sample benchmarks.

How can an organization verify manufacturer reliability?

Contact customers with similar model sizes and deployment locations. Check firmware updates, security controls, warranty limits, and technician response times. References can still be incomplete.

Which delivery and support questions deserve attention?

Ask who handles failures during nights and weekends. Confirm response times, spare-part availability, and missed-delivery consequences. That answer matters.

Conclusion

Choosing the right machine learning server manufacturer requires more than comparing prices or advertised specifications. Organizations should first define their workloads, including model size, training frequency, data volume, storage needs, networking requirements, and expected user demand. These factors help determine the appropriate processing power, memory, accelerators, cooling capacity, and expansion options. It is also important to compare performance, scalability, operating system support, software compatibility, and integration with existing infrastructure.

A dependable manufacturer should provide strong build quality, effective security features, transparent warranty terms, responsive technical support, and reliable long-term service. Organizations should evaluate the total cost of ownership, including energy consumption, maintenance, upgrades, licensing, and potential downtime. Before making a final decision, they should verify technical claims through documentation, independent testing, customer feedback, and a practical evaluation when possible. The best choice is the manufacturer that offers a balanced solution aligned with current objectives while remaining flexible enough to support future machine learning growth.
Liam

Liam

Liam is a dedicated marketing professional with a profound expertise in the industry, where he excels at highlighting the unique advantages of our core products. With a keen understanding of market trends and consumer needs, Liam frequently updates our company’s professional blog, providing......